A harness that scores world models, the video prediction models that guess how a scene will move next. It runs on toy physics first, so the harness itself can be trusted before any real model plugs in.
A test bench for world models. It generates small physics clips of three bouncing discs, asks three simple predictor programs to continue each clip, and scores their guesses with six metrics. The scores rank the predictors on a leaderboard, and a static report shows the bars and filmstrips behind each number.
Why it matters
Robot and car teams want to train on video that a world model generates. The sim to real gap, the distance between simulated and real behaviour, decides whether that works. Pixel scores such as PSNR (peak signal to noise ratio) reward pretty frames. This harness adds object permanence and position checks, and proves its ranking on known answers first.
How it was built
Python with numpy and scikit-image, CPU only, offline, under two minutes end to end. A deterministic disc simulator writes 16 episodes of 60 greyscale frames. Metrics cover PSNR, SSIM (structural similarity, a perception shaped image score), flicker, object permanence (the disc count stays right), position error and energy drift. 24 tests pin hand computed values.
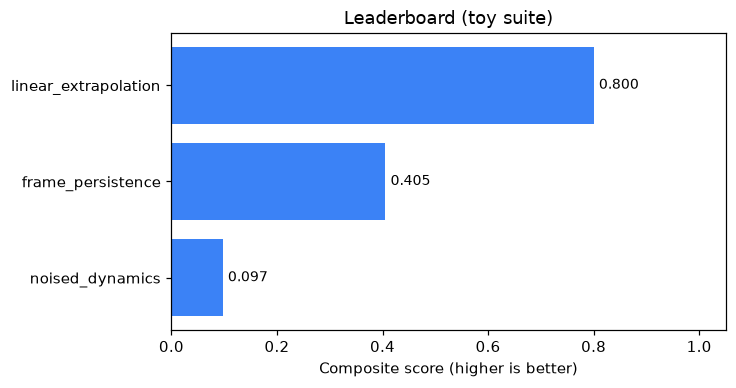
The shipped leaderboard figure, rendered by the report builder from results/toy/leaderboard.json. The composite score rescales each of five metrics so the best model scores 1 and the worst scores 0, then averages the five.
Problem
A realistic looking clip can still break physics.
In my judgement, AI labs now sell video generation models to robotics and driving teams as world models, with no shared scorecard behind the claim. A team that wants one for simulation or synthetic training data has to trust demo clips. The usual video quality metrics measure pixel fidelity, and a model can score well on them while objects vanish, merge or drift between frames.
Building the scorecard against a frontier model first hides a second problem. When a score comes out low, nobody can tell whether the model failed or the harness did. I wanted a harness whose own behaviour was proven before it judged anything real.
What it does
Sixteen episodes, three baselines, six metrics, one ranking.
The harness takes a suite config, generates 16 episodes of three discs bouncing under gravity in a 64 by 64 frame, and hands the first 12 frames to each model. Each model returns 48 predicted frames and, where it can, predicted disc states. Six metric functions compare prediction to ground truth per episode, a composite ranks the models, and a static report shows bars, distributions and filmstrips.
Generates a deterministic suite where the same config and seed produce byte identical npz files and manifest, with no timestamps anywhere. toyworld/generate.py, tests/test_generate.py
Accepts any model that matches a fixed code interface saying which functions a model must provide, checked at runtime, and ships three known-answer baselines behind it. WorldModel Protocol. adapters/baselines.py
Computes six metrics per episode with exact formulas and tests against hand computed values, for example PSNR 28.1308 dB on an all zeros versus all tens pair. metrics/frames.py, metrics/states.py
Ranks models by a min-max normalised mean of five metrics and keeps energy drift out of the composite, so a frozen model cannot win by conserving energy for free. harness/leaderboard.py
Builds a static HTML report with a leaderboard bar, five metric bars, per episode distributions and two filmstrips, offline on a laptop. report/build.py
Solution
Calibrate the harness on known answers, then open the seam for real models.
Ground truth comes from a deterministic disc simulator, bit identical on the same seed. It steps gravity, wall reflection and disc to disc collisions numerically at 30 frames per second, and a test holds its energy leak below 5 percent over 60 frames. Three baselines with a known quality order validate the harness: linear_extrapolation continues each disc in a straight line, frame_persistence repeats the last context frame, and noised_dynamics runs the true simulator with Gaussian noise added to every state.
If the composite ranks those three in the expected order, the harness is doing its job. Five metrics enter the composite and energy drift stays outside it as a diagnostic, since a frozen frame conserves energy perfectly. Two filmstrips, episode 0 and the worst episode for the winning baseline, let a reader see a failure instead of only reading its number.
Result
The baselines rank in the expected order, and two metrics behave in ways I did not predict.
On the toy suite the composite places linear_extrapolation first at 0.800, frame_persistence second at 0.405 and noised_dynamics third at 0.097. A test asserts this order on a small suite. The winner is last on object permanence at 0.69, because it ignores collisions and lets discs overlap into one blob. noised_dynamics invents energy at 30.55 times the starting value, while the frozen frame drifts by exactly zero.
Episodes
16
Composite, best
0.800
State error k10
5.03 px
Tests
24
One row per metric, one column per baseline, values from the shipped result JSON. The winner takes four of the five composite metrics. The frozen frame wins object permanence and energy drift, which is why energy drift stays out of the composite (dashed). The noised simulator beats the winner on object permanence, a result I had not expected.State error is stored at k = 1, 5, 10, 20 and 48 for every model, and only k = 10 enters the composite. Straight line extrapolation wins the short horizon and meets the frozen frame at 23.2 px by k = 48, where a disc that has been left where it was is as good as one that ignored every bounce.
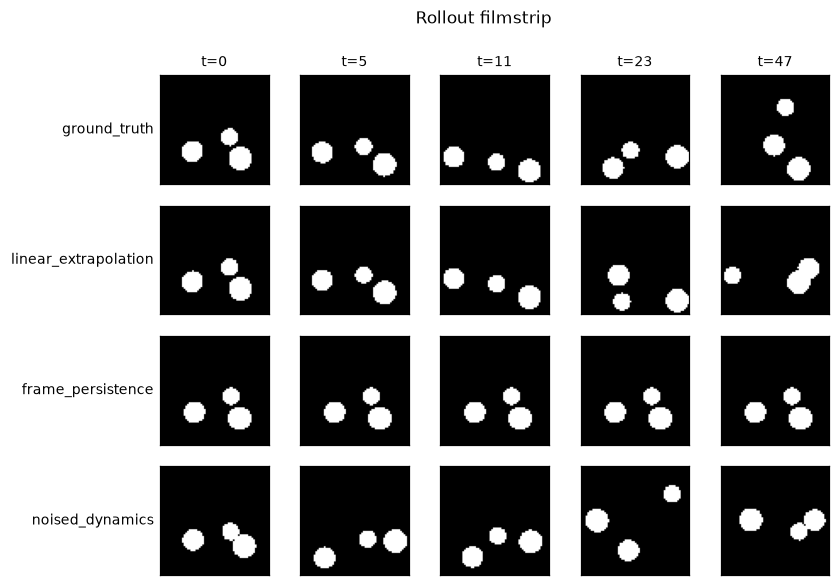
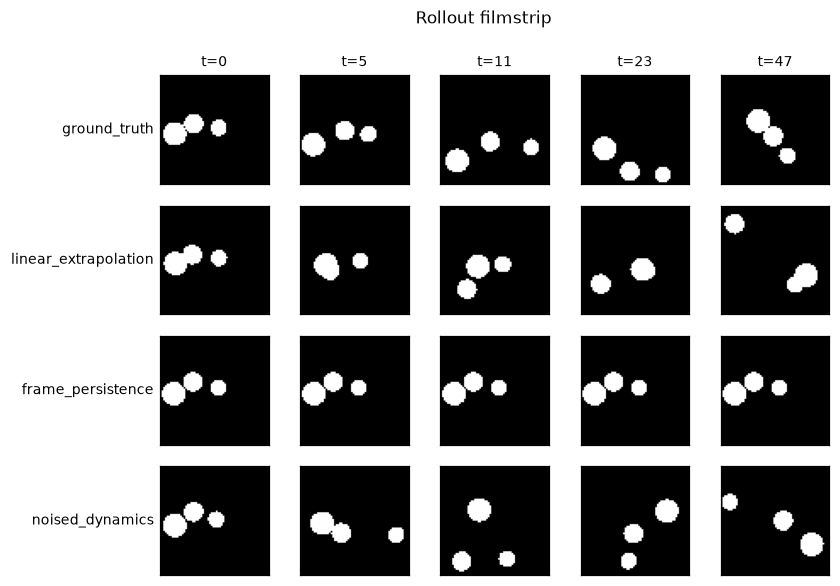
Episode 0. Ground truth on top, then the three baselines across the 48 predicted frames.Episode 12, the worst episode for the winning baseline. Discs that bounced in the ground truth keep going in a straight line.
6 metric functionsPSNR, SSIM, flicker deviation, object permanence, state error at k, energy drift
scikit-imageBSD 3, SSIM and connected components
composite leaderboardmin-max per metric, mean of five, energy drift excluded
predictions and per episode metrics
Engineown code, Python
wmb CLIgenerate, evaluate, report, plus data for the v2 stubs
evaluation runnerloads episodes, runs each model, aggregates, caches rollouts as deterministic npz
numpy, pydantic, pyyamlBSD 3, MIT, MIT
result JSON and leaderboard
Outputs and interfaceswhere a reader lands
results JSON + leaderboard.jsonschema_version 1, metrics and per episode values per model
static HTML reportleaderboard bar, five metric bars, distributions, two filmstrips, metric notes
jinja2, matplotlibBSD 3, PSF style licence. Agg backend, no display
Built in this projectThird party
Sources: numpy, scikit-image and jinja2 are BSD 3, pydantic and pyyaml are MIT, matplotlib carries its PSF style licence. The v2 data stubs point at NVIDIA's TokenBench on HuggingFace, PhysBench (ICLR 2025) and the CARLA 0.9.15 client (MIT, server required), and none of them is exercised. Everything else is this project. The repo licence is still marked TBD in pyproject.toml.
Why it matters
A benchmark can be validated before it judges anything real.
Three predictors with a known quality order come out in that order on the composite, and a test asserts it. Each metric has an exact formula and a unit test against a hand computed value, such as 28.1308 dB for PSNR on a known pair. Energy drift stays out of the composite because a frozen model conserves energy for free, and the report says so. Suite regeneration is byte identical on the same seed. The limits are stated here: toy discs, three baselines, and no frontier model evaluated.
In five years
Teams buying or training world models for robots and cars will run them through standard physics scorecards before trusting their video for training. Those scorecards will need known-answer baselines and per metric diagnostics so a bad score can be traced to a cause. This harness is a small early version of that scorecard.
How it was built
A charter, an empty scaffold, a spec, then one build day.
Python
1,860live lines
Tests
24
Commits
22
Build span
182days
Active days
5
Runtime deps
6+16 optional
Spec, metric formulas, acceptance criteria and review by hand. Implementation with Claude Code agents. All benchmark code landed in twelve commits. The live line count is 1,860 of 3,345 tracked Python lines, excluding 525 lines of early scaffold that nothing imports, 462 test lines and 498 lines of data and utility scripts. No CI. Measured from the repository.
The repo started as a charter for a six dimension frontier model benchmark that did not exist. A later scaffold added metric class skeletons with no metric math and a config that named a checkpoint from Cosmos, NVIDIA's world model. The spec that followed called that out, left the legacy files untouched and defined the toy track with 12 acceptance criteria and 24 named tests. The agent run built it in twelve commits, from config and deterministic npz writer through simulator, baselines, runner, report and tests. The shipped noise defaults produce the expected baseline ordering, so the ordering test passed without retuning.
Algorithms and math2D disc physics with restitution and positional correction, energy accounting, SSIM and PSNR, second difference flicker, connected component permanence, min-max composite. No learning.
Systems integrationSix pure Python libraries, a jinja2 template as package data, matplotlib forced to Agg, an uncompressed numpy archive writer, so two runs produce byte identical result files, an argparse CLI. No services, no GPU.
Data and domainThe world model evaluation literature, why a frozen model games flicker and energy, and why state error stands in for downstream utility.
Evaluation rigorHand computed metric values, a byte identical regeneration test, known-answer ordering as calibration, ground truth energy validation. Only 24 tests, no CI, and per metric winners have no test.
Interface and productThree subcommand CLI and a static jinja2 report with nine PNGs and metric notes. No interactive viewer.
Difficulty 13 of 25 · IntermediateRelative to one competent engineer building it alone
Success criteria
When this counts as working.
The three baselines score in the predicted order on the composite. A test asserts it, and the shipped run passes.
State error grows with the horizon and SSIM falls along the baseline order, which is consistent with the baseline design. Only the composite ordering is asserted in a test, and I have not written tests for the per metric trends or winners.
A filmstrip exists for episode 0 and for the worst episode of the winning baseline, and rollouts for all 16 episodes are cached so any episode can be rendered.
The harness is designed so a real model adapter could plug in through that same interface without touching the scoring pipeline. No real adapter has been built.
Suite regeneration is byte identical on the same seed. Ground truth comes from a deterministic simulator, and the test hashes every npz and the manifest.
Metrics, KPIs, evals
Six metrics, five in the composite.
Model
Composite
PSNR (dB)
SSIM
Flicker
Obj. perm.
State err. k10 (px)
Energy drift (diag.)
1linear_extrapolation
0.800
11.52
0.72
0.009
0.69
5.03
0.74
2frame_persistence
0.405
9.88
0.67
0.044
0.86
11.33
0.00
3noised_dynamics
0.097
9.72
0.67
0.095
0.77
13.40
30.55
Metric
Category
What it catches
PSNR
reconstruction
Peak signal to noise ratio, basic pixel fidelity. A model that cannot get pixels roughly right fails here first. A sanity check rather than the interesting metric.
SSIM
reconstruction
Structural similarity, a perception shaped score that allows small shifts. More forgiving than PSNR.
Flicker deviation
temporal
Frame to frame smoothness compared with the ground truth's own smoothness. Jittery output scores badly here even when single frames look fine, and a frozen frame is measured against the truth so it cannot score perfectly.
Object permanence
structural
Share of predicted frames in which the connected component count matches the three discs. A model that spawns, merges or drops objects fails this even when each frame looks good.
State error at k=10
predictive
Mean position error in pixels ten frames out. This is the test of whether the model predicts. Values at k = 1, 5, 20 and 48 are stored as well.
Energy drift
diagnostic
Relative change in total mechanical energy over the horizon. High drift means the model invents or destroys energy. Reported next to the composite and never mixed into it.
What this does not do yet.
Real model adapters. v0.2 tests the harness on three baselines. The roadmap names Cosmos tokenizer reconstruction, PhysBench and CARLA ground truth as the v2 adapters, and their downloaders are untested stubs.
Filmstrips for every episode. The report renders two, episode 0 and episode 12. Rollouts for all 16 episodes and three models are cached as npz, so the rest can be rendered without rerunning.
Byte identical evaluation output. Suite generation is byte identical and tested. Result JSON and leaderboard.json carry a timestamp, so two evaluation runs differ in that field.
Continuous integration. The 24 tests run locally in about 1.3 seconds, and no CI workflow is in the repo.